- What we offer
- Who we serve
- Digital Transformation
- Our Approach
- Careers
- About Us
- Insights
- Contact Us
Manual financial spreading remains a major capacity constraint inside most commercial real estate (CRE) lending operations.
In its 2025 Commercial Real Estate/Multifamily Finance Annual Origination Volume Summation, the Mortgage Bankers Association (MBA) reports: “Total commercial real estate (CRE) mortgage borrowing and lending is estimated to have totaled $706 billion in 2025, a 40 percent increase from the $505 billion in 2024, and a 65 percent increase from $429 billion in 2023.”
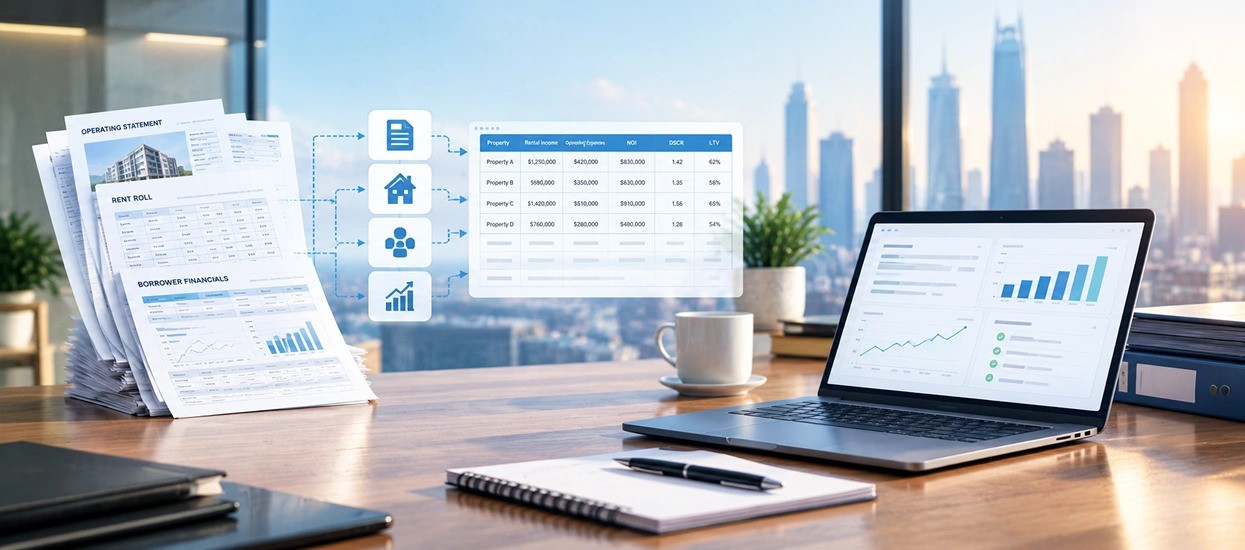
That volume runs into a workflow that has not modernized in step. Analysts still enter rent rolls, operating statements, and borrower financials into templates one field at a time. In this blog, we look at where manual spreading is quietly costing CRE lenders analyst capacity, portfolio consistency, and regulatory ground, and why treating it as a data engineering problem, not a data entry problem, is what recovers all three.
Financial spreading is how borrower financial data moves from source documents into a template that credit teams then analyze.
The template usually holds a property-level operating statement, rent roll, sponsor financials, and any stress-test overlays. Every debt service coverage ratio (DSCR), loan-to-value (LTV), and net operating income (NOI) that follows draws from those cells, as do the records credit committees and regulators eventually see.
Whatever the analyst gets wrong at the source carries through to every downstream calculation and report.
The losses from the variability distribute across the underwriting process rather than concentrating in a single line item, which is why they are so often visible individually and rarely aggregated.
The five patterns below show where credit capacity gets spent on work that could have been avoided.
Every hour an analyst spends on manual data entry is an hour subtracted from the work that only the analyst can do, and the cost of that substitution grows with every additional deal in the pipeline.
Credit teams have known the costs of manual financial spreading for years, but the practice has held on anyway, and the reasons are operational rather than technological.
Borrower documents arrive in inconsistent formats, templates differ by property type, and the interpretive knowledge needed to spread each borrower’s financials cleanly still sits with individual analysts.
On top of that, loan origination systems were built around manual entry from the start. Undoing that design requires aligning underwriting, credit, and portfolio teams on a single categorization standard, which is exactly the kind of change management most institutions have avoided.
That absence of alignment is not something regulators tolerate. In its Interagency Statement on Prudent Risk Management for Commercial Real Estate Lending (SR 15-17), the Federal Reserve, together with the FDIC and the OCC, states: “[…] the agencies are issuing this statement to remind financial institutions to maintain underwriting discipline and exercise prudent risk management practices that identify, manage, monitor, and control the risks arising from their CRE lending activity.”
Underwriting discipline that varies analyst by analyst is exactly what the guidance names as unacceptable.
Inside credit teams, manual financial spreading is often defended as the price of analyst judgment at the source, but that defense confuses two different activities. Neither data extraction nor categorization inside a defined chart of accounts is judgment.
Real analyst judgment sits well above the spread, in the translation of numbers into risk view, covenant design, and portfolio positioning.
Every hour an analyst spends on manual data entry is an hour subtracted from the work that only the analyst can do, and the cost of that substitution grows with every additional deal in the pipeline.
Buying a new tool will not fix the problem on its own. The credit operations that solve it make four coordinated changes, in sequence.
The value of moving off manual financial spreading is not speed alone, but a portfolio-wide credit dataset credit committees and stress tests can actually rely on. Silverskills has made a related case for integrated digital applications in strategic underwriting that carry data cleanly from initial screen through credit memo.
Consider this illustrative scenario from one regional CRE lender’s underwriting operation.
Not every rollout lands this way. Failures repeat across lenders in a handful of patterns, and recognizing them early is what keeps a rollout on track. The five below are the ones that come up most often.
CRE lending operations that treat financial spreading as a data engineering problem, not a data entry problem, unlock underwriting capacity that manual workflows systematically consume.
Read together, those failure modes point at the same underlying shift. CRE lending operations that treat financial spreading as a data engineering problem, not a data entry problem, unlock underwriting capacity that manual workflows systematically consume.
Chart of accounts standardization, exception routing, and change management have to move with the automation itself for that gain to hold. The discipline also extends downstream, in the same way that clean closing data shapes the entire integrated digital CRE loan servicing lifecycle that follows origination.
At Silverskills, we work with heads of underwriting, chief credit officers, and portfolio leaders to modernize financial spreading through standardized coding, AI-enabled extraction, and cleaner downstream credit data.
Our commercial real estate services cover debt and equity underwriting, servicing and asset management, valuation, and securitization. Request a consultation to explore how a modernized spreading operation could take shape across your CRE book.
What is financial spreading in CRE lending?
In CRE lending, financial spreading is the practice of taking a borrower’s financial documents and organizing their numbers into a standardized template used for credit analysis. That template usually covers the property-level operating statement, the rent roll, sponsor financials, and any stress-test overlays for the deal. From it come the DSCR, LTV, and NOI figures that drive credit decisions, along with the records that eventually reach credit committees and regulators.
What does manual financial spreading actually cost a CRE lender?
The labor line is only part of the total. Deals queue behind the spreading step, senior analysts spend their hours on extraction rather than analysis, and two analysts working on the same borrower rarely produce identical spreads. Reporting cycles lag because spread data has to be reassembled by hand each time, and audit exposure grows when the source trace is incomplete. The aggregate effect is a cost that moves out of the labor line and into the credibility of the credit analysis itself.
Why does manual spreading persist in CRE despite the operational cost?
The reasons are operational, not technological. Borrower documents arrive in inconsistent formats across property types and sponsors, and the interpretive knowledge needed to spread them cleanly sits with individual analysts rather than in written policy. Loan origination systems were designed around manual entry to begin with. On top of that, agreeing a single categorization standard across underwriting, credit, and portfolio teams is a change management effort most institutions have not yet undertaken.
What do CRE lenders need to change to automate financial spreading successfully?
The change is not deploying a tool. It is four moves taken together: agreeing categorization rules across underwriting and credit before extraction goes live, routing routine fields to automated extraction with analyst review at the exception, treating each spread record as a data asset with its source and reviewer trail attached, and reallocating the analyst hours that automation frees. The last move matters as much as the first three. Freed capacity dissipates unless credit leadership names in advance where it goes.
What are the common failure modes when CRE lenders automate financial spreading?
Five patterns come up repeatedly. Automation gets built against categorization rules that live in team practice rather than in a written spec, and the vendor ends up encoding whichever version they were shown. The exception workflow gets treated as optional, and the process falls back to full manual on the cases automation was meant to help. Sponsor-level knowledge stays in analyst notes instead of moving into the extraction rules. Speed becomes the only metric, and accuracy drifts unnoticed underneath it. Change management gets underinvested, so the downstream users of spread data stay on the old process while the front end changes.
How does spreading automation affect analyst judgment in CRE credit decisions?
Automated spreading relocates analyst effort rather than removing analyst involvement. Routine data entry and standardized categorization move to the automation layer, and analyst time concentrates on the exceptions: unusual line items, sponsor-specific patterns, and cases where extraction confidence is low. Above that, analyst judgment continues to sit where it always has, in translating the numbers into risk view, covenant structure, and portfolio positioning.

Please fill the details below. A representative will contact you shortly after receiving your request.